Algorithms
Seven strategies. Each one is documented the same way: what it is for, how it actually works, the exact defaults, and where it breaks.
Everything on this page is read from the implementation. Where the code diverges from the textbook description — and in a few places it does — that is called out, because the divergence is the part that will bite you.
Choosing one
| If the space is… | Use |
|---|---|
| Finite and under ~10⁴ combinations | Grid or Brute — exhaustive beats clever |
| Continuous, or very large | TPE or Random |
| Smooth, with a broad basin | SA |
| Large budget, and you want population search | GA |
| Two objectives you cannot trade off | NSGA-II |
TPE is the default and the right general-purpose answer for a single objective.
Grid
For: exhaustive coverage of a finite space, in a fixed deterministic order, exactly once each.
How it works. There is no search loop at all. At initialize() the entire cartesian
product is materialised as an array in memory, and each suggest() simply returns the next
pre-built row.
initialize → product = enumerateCartesian(space)   // the whole space, up front
suggest()  → product[idx++]
report()   → trialsDone += 1
shouldStop() → idx >= product.length | budget reached | time budget reached
The algorithm never looks at the score. report() increments a counter and discards both
arguments. The “best” is tracked entirely by the engine. Grid is pure bookkeeping between
trials.
Row order is odometer-style: the rightmost axis increments fastest.
| Knob | Default | Meaning |
|---|---|---|
budget.maxTrials | Infinity | Stop after this many trials |
budget.maxRuntimeMs | Infinity | Stop after this much wall-clock |
| (algorithm config) | {} | Grid reads no algorithm config keys |
Two hard limits, and they fail loudly
1. The space must be finite. If any axis has more than 10 000 values — most
notably a fine-stepped float — initialize() throws:
“GridOptimizer: search space is not finite — use TPE/SA/GA/Random instead.”
2. The space must be under 50 000 combinations. The running product is set to
Infinity as soon as it crosses that line, which clears the
finiteSearchSpace flag and trips the same check.
Both produce an error, not a truncated run. A partial exhaustive search that reported itself as exhaustive would be far more dangerous than a refusal.
Edge cases worth knowing
- All parameters excluded → the product is empty and the run does zero trials. It is not an error; it simply ends immediately.
- Budget smaller than the space → the run is truncated. Grid has no stop-reason field, so no distinct reason is reported.
- A dimension with zero choices → one row is emitted with an
undefinedvalue, which fails validation. The result is 0 committed trials and 1 rejected suggestion — a run that appears to have done nothing. - Memory is O(product length), because the product is built up front. At 50 000 rows that is fine; it is still a full materialisation.
Brute Force
For: the same exhaustive coverage as Grid, presented as a distinct choice.
How it works. Functionally identical to Grid. The single structural difference is an
order indirection over the product:
order = product.map((_, i) => i)   // the identity permutation
suggest() → product[order[idx++]]
The indirection exists so that randomising the trial order is a later change. Today it
changes nothing — the order is [0, 1, 2, …].
Everything else — the finiteness gate, the 50 000 feasibility limit, the edge cases, the absence of a stop reason, the non-resumable snapshot — is identical to Grid.
Random
For: uniform sampling for a fixed trial count, and the honest baseline every other method should be measured against.
How it works. Each suggest() draws a uniform sample, checks it against a bounded
recent-history set, and returns it if unseen — retrying up to 32 times, then returning a
fresh sample unconditionally as a fallback.
suggest() → for up to 32 attempts: draw; if unseen, remember and return
            otherwise: draw once more and return it regardless
report()  → trialsDone += 1
shouldStop() → budget or time budget reached   (never a space bound)
The algorithm never looks at the score. Every suggestion is returned regardless of how good it was. All the learning happens in TPE and GA instead.
| Knob | Default | Meaning |
|---|---|---|
dedupeWindow | 1 000 | Size of the recent-history ring buffer |
budget.maxTrials | Infinity | Trial budget |
budget.maxRuntimeMs | Infinity | Time budget |
| resample attempts | 32 | Hardcoded, not configurable |
| condition attempts | 32 | Hardcoded, not configurable |
The dedupe window, precisely
It is a ring buffer of the last dedupeWindow signatures, oldest evicted
on every push. It is not a permanent “have I seen this” set.
Membership is a linear scan over up to 1 000 strings per draw. The signature sorts the value keys and stringifies them, so it is order-independent — but it is built from raw values with no step-granularity snapping, so two float draws differing in their last bits count as distinct. (Compare the identity key used by SA, which does snap.)
The window is written at proposal time, before the trial runs — so a trial later rejected by validation has still consumed a slot.
Random and NSGA-II are the algorithms that honour conditional parameters
evaluateConditions is reached from the random sampler and from NSGA-II’s
proposal path. Grid, Brute, SA and GA do not consult it, and the value validator does not
either.
So a Grid or Brute run over a space with conditional parameters will happily produce trials that violate the condition — they are still type- and range-checked, so the run completes and the numbers look legitimate.
Cost profile. Produces exactly maxTrials trials, independent of space size — the most
predictable of the seven. Best on continuous or enormous spaces where enumeration is impossible,
and on small budgets. Worst on small finite spaces, where it wastes budget re-sampling points
Grid would cover exactly.
Simulated Annealing (SA)
For: a single local walk through the space, where occasional worse moves are accepted so the search can escape a local optimum.
How it works. Every trial is a neighbour of the currently accepted point, drawn from the shared neighbourhood function. A candidate is accepted if it is at least as good; otherwise it is accepted with a Metropolis probability that decays with temperature.
// acceptance, maximising on pnl
if (current == null || current.pnl == null) accept = true        // first scored trial
else if (pnl >= current.pnl)                   accept = true        // ties accepted
else {
  const delta     = current.pnl - pnl
  const threshold = Math.exp(-delta / Math.max(T, 1e-300))
  accept = rng.next() < threshold
}
Cooling is a single geometric decay applied after every scored trial, accepted or not:
T = Math.max(minTemperature, T * coolingRate)The run stops when the temperature reaches its floor — so the trial count is largely determined by the schedule, not by your budget.
| Knob | Default | Meaning |
|---|---|---|
initialTemperature | 1.0 | Starting temperature |
coolingRate | 0.95 | Per-trial multiplier — clamped to [0.85, 0.99] |
minTemperature | 1e-3 | The floor that ends the run |
maxResampleAttempts | 16 | Neighbour resamples before a uniform fallback |
fallbackWarnThreshold | 64 | Consecutive fallbacks before one warning |
budget.maxTrials | Infinity | Trial budget |
budget.maxRuntimeMs | Infinity | Time budget |
The trial count is set by the schedule, not your budget
With the defaults, T ← 0.95 × T reaches the floor of 1e-3 after
135 scored trials:
ceil( ln(1e-3) / ln(0.95) ) = 135
Generally: ceil( ln(minTemperature / initialTemperature) / ln(coolingRate) ).
Set a softer coolingRate of 0.99 and you get roughly 1 384
trials — a tenfold budget increase from one config change.
This is a genuine gotcha: a user who sets a 1 000-trial budget on an SA run watches it stop at 135, because cooling is not skipped for rejected or failed trials.
Three places this implementation differs from the textbook
1. The initial uniform sample is never evaluated. The seed is added to the visited
set immediately, and suggest() only ever returns a neighbour of the current
point. So the first trial is a neighbour of a uniform sample, and the uniform sample
itself is discarded unscored. The first scored trial is accepted unconditionally, and
becomes the starting current point. The file’s own header describes the seed as being
evaluated — the code does not do that.
2. Acceptance is non-strict. Ties (pnl >= current.pnl) are accepted.
The header comment says “strictly improving”; the comparison is >=.
3. It anneals continuously and never restarts. There is no reheat, no restart and no multi-phase logic anywhere in the implementation — a single monotonic decay.
When SA degrades into random search
SA is the only algorithm here with an unbounded visited set — one entry per proposal, for the life of the run, with no eviction.
On a small or integer-only space, neighbour proposals saturate: after 16 collisions SA takes a uniform global fallback instead of a local step. After 64 consecutive fallbacks it emits exactly one console warning, once per run, and then stays quiet — so a silently degraded run looks identical to a healthy one from the UI.
Cost profile. Trials ≈ min(maxTrials, schedule length, space exhaustion). Best on
medium-dimensional spaces with real numeric gradients. Worst on very wide float ranges —
its float step size is a fixed fraction of the range, so a wide dimension takes many trials to
traverse — and on tiny integer-only spaces, via the saturation path above.
TPE
Tree-structured Parzen Estimator. The default method, and the right general-purpose answer.
For: large, continuous, or high-dimensional spaces where enumeration is impossible.
How it works. TPE keeps two probability models of each parameter — one fitted to the best trials, one to the rest — and generates candidates that score well under the first while scoring poorly under the second.
initialize → adapt the space into integer-indexed dimensions
           → seed from job.seed (NOT the constructor rng)

suggest()  → if fewer than `warmupEligible` eligible trials: draw uniformly
           → else: build good/bad groups, draw `nProposals` candidates,
             score each, return the best-scoring unseen one

report()   → record pnl, mark eligible/ineligible, track the best
shouldStop() → budget | time | space exhausted| Knob | Default | Controls |
|---|---|---|
warmupEligible | 20 | Eligible observations required before the model is used at all |
gamma | 0.20 | Fraction of trials forming the good group |
nProposals | 24 | Candidates drawn and scored per suggestion |
uniformWeight | 0.1 | Weight of the uniform component mixed into each numeric density |
seed | null | Seeds the internal generator; job.seed overrides it |
The density model
Every parameter becomes an integer-indexed dimension, and a candidate is an array of
per-dimension indices. Booleans get two slots; categoricals get one per choice; numerics get
floor((max − min) / step) + 1 slots. A dimension with a non-finite or inverted
range is silently dropped, as is any parameter of an unrecognised type.
Numeric density is a Gaussian kernel density estimate with a 10 % uniform mixture, evaluated on the value scale:
kde   = (1/n) · Σ exp(−0.5·u²),  u = (x − sᵢ)/bw
uni   = 1 / max(hi − lo, 1e-12)
mixed = (1 − α)·kde + α·uni,  α = 0.1
return log(max(mixed, 1e-300))
That is a linear mixture of densities — the logarithm is taken once, after mixing, not per component.
Bandwidth is Silverman’s rule, floored:
silver = 1.06 · σ · n^(-0.2)
bw     = max(silver, (hi − lo)/50, 1e-6)
Categorical and boolean density is a histogram with a +1 Laplace pseudocount on
every possible value, not only the observed ones — so an unobserved choice keeps
probability 1/(n + k) and stays reachable for the whole run. That is a
deliberate safeguard: without it, a choice that never appeared in a good trial could never
return.
The good/bad split is a hard fraction, not a gamma rule
const gammaN = Math.max(1, Math.floor(cfg.gamma * n))
good = indexed.slice(0, gammaN)      // top 20 %, at least one
bad  = indexed.slice(gammaN)
At the moment warm-up ends, with 20 eligible trials, that is 4 good and 16 bad.
There is also a flat-objective guard: if every eligible trial has an identical score, both groups come back empty and the proposer falls back to uniform sampling. Without it, a meaningless objective would produce a confidently meaningless model.
Half of all proposals are plain uniform draws
This is the largest divergence from textbook TPE, and it changes what the method is.
Standard TPE draws every candidate from the good distribution and ranks by
log l(x) − log g(x). This implementation flips one coin per candidate:
with probability ½ the candidate is a pure uniform draw across every dimension, not a
perturbation of a good observation.
With nProposals = 24, roughly 12 of the 24 candidates are uniform, and
they compete on equal terms with the good-perturbed ones. The surviving candidate is
therefore frequently a uniform sample.
The source code acknowledges this as a deliberate hybrid. Whatever the merits, it means “TPE” here is a 50/50 blend of model-guided and blind sampling — which is part of why it behaves so much like Random on small spaces.
The score has an undocumented per-dimension cap
s += lg - Math.max(lb, lg - 50) // accumulated per dimensionAny dimension where the “bad” density underflows contributes at most 50 to the score, so a single saturated dimension cannot give a candidate an unbounded advantage.
This clamp appears in no textbook formulation of TPE and is not in the module’s own specification comment. It is a sound engineering guard, but it is undocumented behaviour you should know about if you ever need to reason about why one dimension dominated a parameter’s importance score.
Three things that do not exist in this implementation
- Log-scaled dimensions. There is no log transform anywhere — no logarithm on the value axis, no scale property read, no back-transform. A repository-wide search finds only a stale comment describing log-jitter, sitting above a float branch that jitters linearly. Parameters spanning several orders of magnitude are handled on a linear scale, which is a real limitation for threshold-style strategies.
- Warm-starting from the best. Never happens.
- Exact KDE sampling. Despite a KDE being fitted, the perturbation is a fresh Box–Muller draw around one randomly chosen good observation, with the bandwidth recomputed per dimension per proposal — not an exact sample from the fitted density.
Cost profile. Each suggestion costs 24 candidate scorings, and the 24-proposal budget is spent on unseen candidates only — so the effective pool shrinks as a run proceeds. If every proposal collides, the proposer returns nothing and the run falls back to uniform sampling. Ties resolve to the first proposal seen, so RNG order decides.
Genetic Algorithm (GA)
For: large budgets, spaces where population search is affordable, and — uniquely among the single-objective algorithms — parallel execution.
How it works. A population of parameter sets is evaluated each generation, the best are carried forward unchanged, and the rest are replaced by children produced by tournament selection, crossover and mutation.
initialize → build an initial population (seeded from your config, then uniform)
           → split the trial budget between evolution and local refinement

suggest()  → hand out an unemitted individual from the current generation
           → when the generation is spent, advance and build the next one

report()   → match the result back to its slot BY KEY, not by position
shouldStop() → budget | time | generations exhausted | local grid complete| Knob | Default | Controls |
|---|---|---|
populationSize | 30 | Individuals per generation |
generations | 50 | Generation cap |
elitism | 2 | Carried unchanged into the next generation |
crossoverRate | 0.70 | Probability of crossover vs. asexual clone |
mutationRate | 0.10 | Baseline per-gene mutation probability |
tournamentSize | 3 | Tournament size |
adaptiveMutation | "auto" | Phase 1 — boost mutation on stagnation |
maxMutationRate | 0.30 | Cap on the adaptive boost |
stagnationGenerations | 5 | Stagnating generations before a boost |
mutationBoostFactor | 1.30 | Per-generation multiplier while stagnating |
mutationRecoveryRate | 0.02 | Decay on an improving generation |
improvementEpsilon | 1e-6 | “Meaningful improvement” threshold |
diversityProtection | "auto" | Phase 2 — detect population collapse |
diversityThreshold | 0.25 | Mean pairwise distance floor |
minUniqueness | 0.60 | Distinct/population floor |
immigrantRate | 0.08 | Fraction of child slots replaced by fresh draws |
localRefinement | "off" | Phase 3 — local grid around the champion |
gridSplit | 0.30 | Budget fraction reserved for the local grid |
localRadiusSteps | 2 | ±N steps around the champion |
gaMinTrials | 50 | Skip refinement if the GA’s share falls below this |
Selection, crossover, mutation — the exact operators
Selection — tournament, size 3. Three candidates are drawn with replacement, uniform over array positions — not proportional to fitness. The best of the three wins. Selection pressure comes entirely from the within-tournament argmax.
for (let i = 0; i < picks; i++) {
  const idx = Math.floor(rng.next() * sorted.length)
  if (best == null || sorted[idx].pnl > best.pnl) best = sorted[idx]
}
With k = 1 selection is uniform; with k = populationSize it is
pure elitism.
Crossover — uniform, per gene, 50/50, discrete only.
out[p.title] = (rng.next() < 0.5) ? a[p.title] : b[p.title]Because a value is copied wholesale rather than blended, this is type-agnostic: integers, floats, booleans and categoricals all cross without special-casing. There is no arithmetic or blending crossover. If the second tournament returns the same individual as the first, the child is a plain clone.
Mutation — per gene. Each parameter independently passes a coin at the current rate; if it passes, that single gene is perturbed by the same neighbourhood function simulated annealing uses — deliberately shared, so there is exactly one implementation of “how do I move one gene”.
Phase 1 — adaptive mutation
When the best result has not meaningfully improved for 5 generations, the mutation rate is multiplied by 1.30, up to a cap of 0.30. A meaningful improvement decays it by 0.02 back toward the baseline.
Two details make this correct rather than merely reactive:
- The baseline is a floor, never a replacement. The rate is clamped to
[mutationRate … maxMutationRate], so the configured baseline is what you get back. - ”Meaningful” is a hybrid threshold:
ε + |lastBest| · ε. A purely relative test is wrong when the fitness values are negative, because it never fires for losses — and losses are exactly when a stagnating search needs help.
It is decided before the next generation’s children are built, so every child of generation N uses the rate chosen by generation N−1. A whole generation of failures counts as stagnation.
Phase 2 — diversity protection
Two independent collapse measures are computed over the evaluated population:
- Mean pairwise distance — for every pair, the mean over dimensions of the
normalised difference (numerics scaled to their own
[min, max]; everything else compared as Hamming distance). Floor 0.25. - Distinct ratio — unique keys over population size. Floor 0.60.
Collapse is either floor firing, checked independently.
When it fires, 8 % of the child slots are replaced with fresh uniform draws — 3 of 28 by default. The quota is computed before the evolutionary fill so immigrants genuinely occupy slots rather than topping up a short population. Elites are never displaced: they were already committed before the quota is applied.
Phase 3 — local refinement
Off by default. The default was chosen specifically so that existing users’ trial counts do not silently change.
When enabled, a fraction of the budget (30 % by default) is reserved for an exhaustive grid over a ±2-step neighbourhood of the best parameters found. Only the numeric bounds of integer and float parameters are narrowed; the step, the type, and every categorical and boolean parameter pass through unchanged.
The radius shrinks deterministically until the combination count fits the budget, and the grid is enumerated with the same function Grid uses — so it hits the same limits and the same failure mode.
The exact skip threshold, with the defaults:
skip ⟺ B − floor(0.30·B) < 50 ⟺ B ≤ 70At a budget of 71 trials refinement switches on (21 grid, 50 evolutionary). At 70 it is skipped. A budget of 100 gives 30 grid and 70 evolutionary.
Elites are never re-evaluated
The top individuals are carried into the next generation unchanged and never re-run — deliberately, because re-evaluating a known individual would violate the de-duplication contract and waste a full backtest.
One visible consequence: a generation emits populationSize − elitism new
trials, not populationSize. At the defaults that is 28 new trials per
generation, not 30 — so a 50-generation run costs fewer trials than
30 × 50.
Reporting is matched by key, which is what makes parallelism safe
const key = paramsKey(values, parameters)
const slot = pending.find(p => p.key === key) ?? null
Results are matched back to their slot by parameter key, never by position. That is precisely what allows a batched run to report results out of order and still attribute them correctly.
Two more guarantees: a failed or non-finite result is written as −Infinity,
so it can never be selected as a parent; and the best result is monotonic and
independent of the slot match — a late report from a previous generation still updates the
best, even though its fitness is lost to that generation.
A stop-condition bug that was fixed in both algorithms
Earlier versions of this page recorded a defect here: the run stopped at
generation > generations while the stop reason was reported at
>= — so the loop and the reason disagreed by one generation about what the run
actually did.
That is fixed. Both GA and NSGA-II now use >=, and a regression test
asserts generation === generations for several generation budgets across both
algorithms.
It is kept here because the interesting part is why it mattered: the off-by-one was a GA pattern that NSGA-II copied, and the two algorithms are now measured against each other precisely so a silent divergence like that cannot come back.
Cost profile. Expensive per unit of progress: a generation costs a full population of backtests before any child exists. On small spaces this is why it is manual-selection only — it will spend most of its budget before showing an improvement. Its advantages are large-budget robustness and the only route to parallel execution.
NSGA-II
Non-dominated Sorting Genetic Algorithm II. The multi-objective method.
For: when you have two or more objectives that cannot be traded off against each other. Return against drawdown. Profit factor against maximum drawdown. Win rate against trade count. Any pair where “better” is genuinely two-dimensional.
How it works. Instead of collapsing each trial to one number, every trial is a vector. The population is repeatedly sorted into Pareto fronts, and selection picks from the better-ranked fronts with diversity pressure from crowding distance.
It shares GA’s operators and its non-dominated sort, but its selection, mutation and parallel transport are its own code.
Why it exists
Exact defaults
| Knob | Default | Controls |
|---|---|---|
populationSize | 100 | Individuals per generation |
generations | 40 | Generation cap |
crossoverRate | 0.90 | Probability of crossover |
crossoverOperator | "uniform" | Uniform, or "sbx" — the blended operator, numeric parameters only |
sbxEta | 15 | Mixing constant, used only by sbx |
mutationRate | 0.10 | Per-gene mutation rate |
maxResampleAttempts | 16 | Duplicate-proposal resamples |
seed | null | Falls back to the job seed |
constraints | all null | Optional; off by default |
The keys are flat, and the defaults are deliberately bigger than GA's
resolveConfig() reads flat keys — opts.populationSize,
falling back to OPTIMIZER_DEFAULTS.nsga2.populationSize — not an
nsga2.-prefixed block. So populationSize genuinely controls the
population; immigrantRate is GA-only and NSGA-II never reads it.
The defaults are notably larger than GA’s 30 / 50. The reasoning is in
config.js: Deb’s own NSGA-II experiments use 100 for 2–3 objectives, which is
where crowding distance beats tournament selection. The side effect is that 100 × 40 = 4000
exceeds a typical 1000-trial budget, so a standard run usually stops on budget around
generation 10 — well short of the cap. The Pareto panel is therefore a snapshot, not a
finished front.
Objectives
app/js/optimizer/optimizers/nsga-objectives.js decides what a vector is.
| Mode | Behaviour |
|---|---|
| Objectives configured | Builds a real vector, ranked exactly as they are listed |
| One objective | Degenerates to that objective alone, with no second term |
| No objective resolvable | Passes the configured scalar straight through — so NSGA-II behaves as a standard GA |
Parallel execution
NSGA-II proposes a whole generation at once, so it is batched — the same worker-pool path as GA.
| Property | Value | Why |
|---|---|---|
| Pool size | Shared sizing model | Identical to GA; NSGA-II sets no cap of its own |
| Batch size | 4 × worker count | The engine is deliberately given more work per round than it has workers, so the scheduler always has something queued |
How it differs from GA
| Aspect | GA | NSGA-II |
|---|---|---|
| Fitness | Single scalar | Vector |
| Selection | Tournament of 3, uniform over array positions | Non-dominated rank, then crowding distance |
| Parallel | suggestBatch | suggestBatch plus evaluateBatch |
| Result return | Matched to a slot by paramsKey | Matched to a slot by paramsKey |
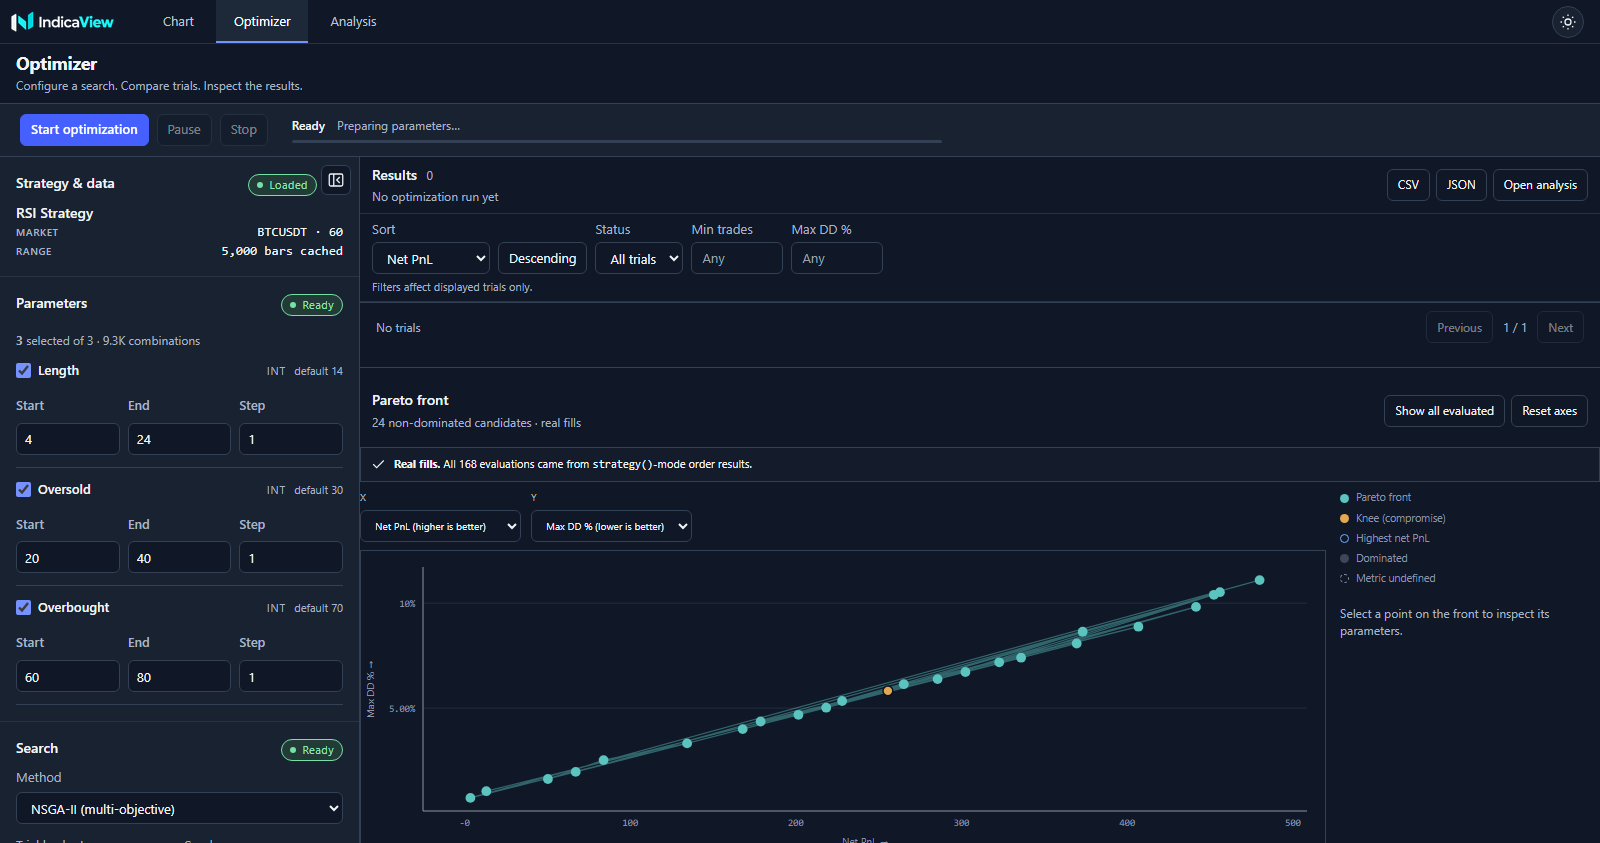
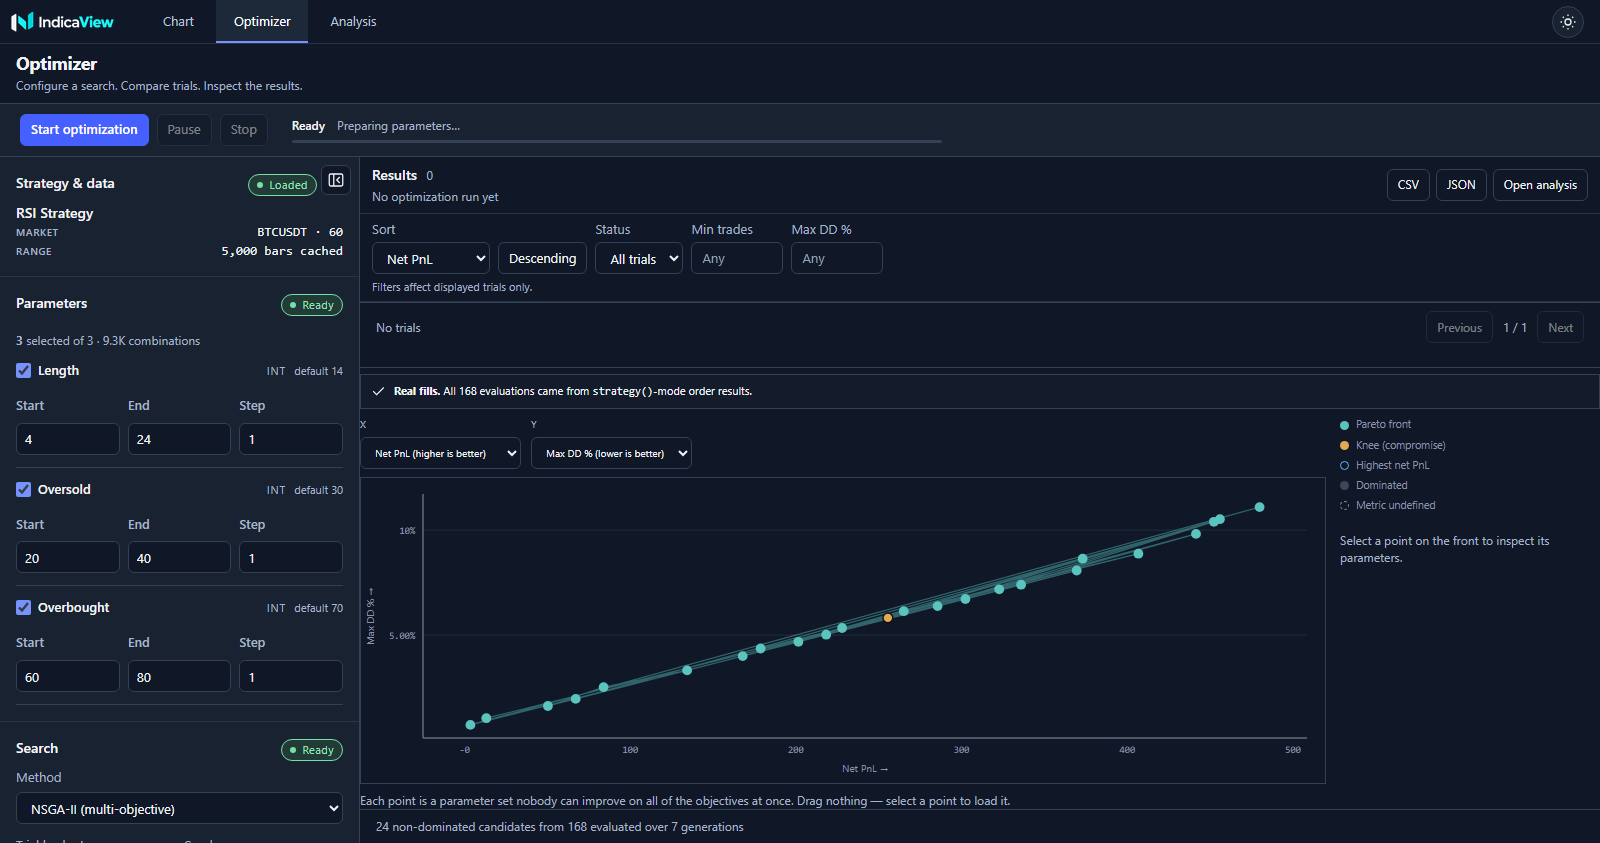
| Exclusive surface | — | Pareto panel |
| Adaptive mutation | mutationRate + boost/decay | Fixed rate, no stagnation boost |
| Local refinement | Optional, ±2 steps | Not implemented |
Why matching by key, not by position
The worker pool finishes a batch in whatever order the workers happen to complete it. So
NSGA-II matches each result back to its slot by paramsKey, never by array
position — the same rule GA uses.
Each slot carries an emitted flag, and a slot counts as available only when
that flag is not strictly true. The strict test is deliberate: a slot built without
the field is still treated as available, so adding a new construction site elsewhere cannot
silently mark a whole generation as already emitted and starve the batch.
What makes a seeded run reproducible is therefore not a return order — there isn’t one — but the combination of key matching and the rule that a batch must never span a generation boundary.
What it does not do
Also worth knowing:
- Crowding is epsilon-only. There is no boundary or objective-space crowding refinement, so diversity pressure is weaker than a textbook implementation.
- Duplicate proposals are repaired by mutation, not re-drawn.
- Adaptive mutation is not implemented — it is a constant rate, so stagnation is not handled the way GA handles it.
Cost profile
Proposing a whole generation at once makes each round wider than a GA round, but the two consume the same trial budget. The practical difference is that an NSGA-II run is more likely to stop on budget before it stops on generations — at the shipped defaults, 100 × 40 = 4000 against a typical 1000-trial budget.
The Pareto panel renders the front, its members and their trial rows in the workspace.
Auto selection
For: choosing a method when you have no strong opinion.
The rules, in order:
| Condition | Chosen |
|---|---|
| Budget under 50 trials | Random — too few observations for a model |
| Space not finite (or over 50 000 combinations) | TPE |
| Finite and ≤ 5 000 combinations | Brute |
| Finite and 5 001 – 50 000 | Grid |
| Nothing above matched | TPE, with a reduced budget |
SA, GA and NSGA-II are never returned.
The fallback is TPE, and an earlier version of this page said Random
chooseMethod() ends in method: ‘tpe’ with a tightened budget. Random is
reached only through the explicit sub-50-trial branch at the top.
That distinction matters: TPE is the one method that keeps learning from a larger budget, so it is the safer fallback when the space does not fit a finite search. Random would simply spend the same budget without improving.
What the UI shows versus what actually ran
Auto keeps your requested method displayed and substitutes the one it actually chose. The method that executed is recorded in the run context.
That is deliberate: silently relabelling the method would make a saved run irreproducible-looking, and would hide the fact that a different algorithm produced the numbers. The discrepancy is visible rather than hidden — but it does mean the algorithm name on screen is not always the algorithm that ran. The run context is authoritative.
Next
- Search space — the dimensions all of this operates on.
- Execution — who runs the trial, and why only one algorithm parallelises.